
Whenever a single vendor captures 80 percent of a highly lucrative market, history tells us two things are about to happen. First, the dominant player will begin to act as if their moat is impenetrable, often prioritizing lock-in and margin over customer flexibility. Second, a hyper-focused challenger will quietly chip away at the foundation of that dominance until the market suddenly realizes a viable alternative has arrived. We saw it when AMD’s Opteron blindsided Intel in the data center two decades ago, and we are watching it happen again right now in the artificial intelligence accelerator space.
For the last three years, Nvidia has been the undisputed king of AI. Its hardware was the standard, and its CUDA software ecosystem was the moat that kept customers from leaving. But in the technology sector, software moats eventually evaporate when hardware performance deltas become too large to ignore.
This week, the MLPerf Inference 6.1 results were released, and they represent a seismic shift in the AI landscape. AMD didn’t just show up to compete; they showed up to win. And for IT buyers and data center architects looking at their 2027 budgets, the realization is setting in: Nvidia is no longer the only safe bet, and in many critical workloads, they aren’t even the fastest one.
The MLPerf 6.1 Breakthrough: Beating Blackwell
To understand why this is a turning point, you have to look at the raw data. The MLPerf benchmark is the industry’s gold standard for evaluating AI performance, cutting through marketing fluff to deliver verified, repeatable results. As detailed in their recent breakdown of the MLPerf Inference 6.1 submission, AMD delivered a masterclass in silicon execution.
The most shocking revelation from the benchmark was the head-to-head performance against Nvidia’s highly touted Blackwell architecture. AMD’s Instinct MI355X GPU actually led Nvidia’s B200 and B300 in GPT-OSS-120B results at the 8-GPU scale. Even more impressively, at the 72-GPU rack scale, the MI355X outperformed Nvidia’s flagship GB200 platform. We are no longer talking about AMD as a “budget alternative.” We are talking about AMD taking the absolute performance crown from Nvidia’s newest, most expensive silicon.
But it’s not just about peak hardware; it’s about software maturation. AMD’s submission proved that their ROCm software stack is finally hitting its stride. On the exact same MI355X hardware from previous testing rounds, continued ROCm optimizations delivered a 38 percent increase in server throughput for GPT-OSS-120B and reduced latency by a staggering 70 percent on the Wan-2.2 text-to-video model.
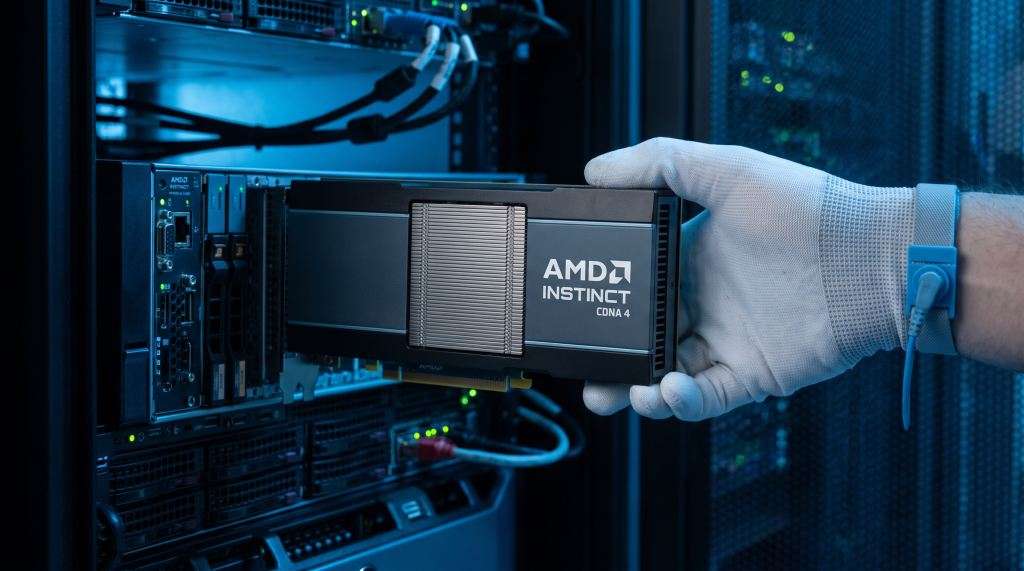
Furthermore, AMD introduced the MI350P, a dual-slot PCIe card built on the CDNA 4 architecture, designed to slot effortlessly into existing data center infrastructure. In its very first MLPerf showing, the MI350P outperformed Nvidia’s RTX PRO 6000 and H200 NVL. Add in partner Crusoe’s massive 512-GPU submission hitting an unprecedented 5.75 million tokens per second, and you have a hardware ecosystem that is scaling flawlessly from single-node edge deployments to massive cloud clusters.
The Power of Singular Focus
Why is AMD pulling ahead? The answer lies in the companies’ respective corporate strategies and CEO Lisa Su’s ruthless execution.
Nvidia, under Jensen Huang, has been trying to build the entire world. They are building CPUs, networking gear, full rack-scale systems, and a proprietary software ecosystem. They want to be the IBM of the AI era—controlling the entire stack top to bottom. While that drives massive margins in the short term, it also creates a massive surface area to defend. It alienates OEM partners who feel relegated to mere resellers, and it frustrates cloud providers who hate being locked into a single supplier’s margin structure.
AMD, on the other hand, has maintained a singular, laser-like focus on one thing: delivering the highest-performing compute engines on the planet. They aren’t trying to lock you into a proprietary networking fabric or force you to buy their rack designs. They are building components – incredibly powerful ones with massive memory footprints like the MI355X’s 288GB of HBM3E – and handing them over to an open ecosystem.
This tight focus on raw performance is why they are winning. In AI inference, memory bandwidth and capacity are the primary bottlenecks. By over-indexing on HBM3E capacity while Nvidia skimped to protect margins and segment their product stack, AMD gave developers the hardware they actually needed for massive models like Llama 3 and GPT-OSS. Raw performance eventually forces software to adapt, and we are seeing the open-source community rally around AMD precisely because the hardware is too good to ignore.
The Path Forward for AMD
Of course, winning a benchmark isn’t the same as winning the market. Nvidia still holds roughly 80 percent of the AI accelerator revenue share as of late 2026. For AMD to fully benefit competitively from these MLPerf results, they have to execute flawlessly on three fronts.
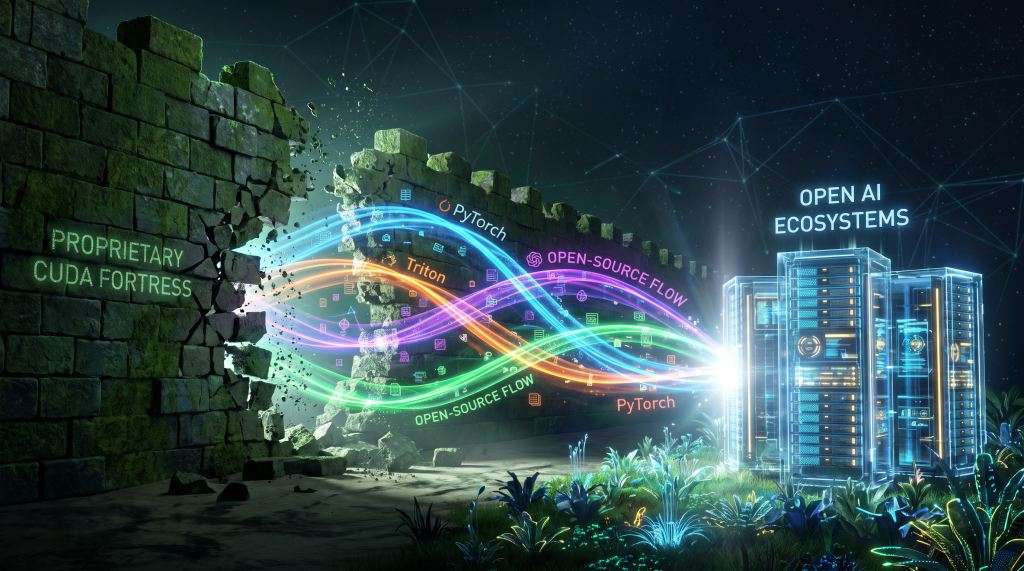
First, they must accelerate the democratization of their software stack. ROCm has improved vastly, but AMD needs to push the industry entirely toward hardware-agnostic frameworks like Triton and the UXL Foundation. The goal shouldn’t be to make ROCm the new CUDA; the goal should be to make CUDA irrelevant. If a developer can write a model once in an open framework and have it run optimally on AMD, Nvidia’s moat vanishes.
Second, AMD needs to aggressively support their OEM and hyperscaler partners. Nvidia’s full-system approach (like the GB200 NVL72) competes directly with server makers like Dell, HPE, and Lenovo. AMD must lean into this friction, providing these OEMs with the reference architectures and engineering support they need to build systems that definitively outclass Nvidia’s proprietary racks. AMD needs to be the ultimate partner, not a competitor to its own supply chain.
Finally, AMD must ensure aggressive and unyielding supply chain parity. The biggest challenge to adopting AMD over the last two years hasn’t always been performance; it’s been availability. AMD must secure enough advanced packaging and HBM volume to guarantee that when a cloud provider wants 100,000 GPUs, AMD can deliver them faster than Nvidia can.
Predicting the Flip: When Will AMD Pass Nvidia?
If AMD executes on this path, the market flip isn’t a matter of if, but when. Technology markets rarely shift overnight, but when they do, the momentum is exponential. Here is the likely sequence of events leading up to AMD passing Nvidia in data center AI accelerator market share.
Phase 1: Hardware Superiority and Proof of Concept (2026). We are in this phase right now. The MLPerf 6.1 results prove that AMD has the superior silicon and that the software is capable of extracting that performance. The early adopters and highly technical hyperscalers are proving that AMD clusters can be deployed at scale without regression.
Phase 2: The TCO Awakening (2027). As the AI market shifts from the training phase (which is highly compute-intensive and heavily reliant on historical CUDA codebases) to the inference phase (which is highly memory-bound and cost-sensitive), Total Cost of Ownership will become the primary driver. With AMD offering significantly more memory per GPU and operating at a lower price point, cloud providers will begin heavily incentivizing customers to use AMD instances. We will see major cloud providers shift their default AI inference offerings from Nvidia to AMD to preserve their own margins.
Phase 3: The Ecosystem Tipping Point (2028). By 2028, the open-source software layer will be completely abstracted from the hardware. A new generation of AI developers will enter the workforce having never written a line of CUDA, relying entirely on high-level frameworks. Nvidia’s software moat will be entirely neutralized. During this phase, enterprise buyers who historically bought Nvidia for “safety” will realize they are overpaying for underperforming hardware. The OEM channel will shift heavily toward AMD to regain control of their own server designs.
Phase 4: The Flippening (2029 – 2030). Sometime around late 2029 or early 2030, the lines will cross. Nvidia will still have a massive installed base of legacy training clusters, but the net-new deployments for inference, enterprise AI, and agentic workflows will heavily favor AMD. AMD will surpass Nvidia in annual AI accelerator unit shipments, and shortly thereafter, in revenue share. Nvidia will be forced to compete on price, collapsing their astronomical margins and permanently altering the dynamics of the semiconductor industry.
Wrapping Up
Nvidia has enjoyed one of the most remarkable runs in the history of the technology industry, but the MLPerf 6.1 results are the writing on the wall. You cannot maintain a proprietary monopoly indefinitely when a competitor is delivering better hardware, scaling it efficiently, and empowering an open-source software movement to tear down your moat.
AMD’s singular focus on performance and execution has successfully neutralized Nvidia’s Blackwell architecture before it could even establish true dominance. The transition won’t happen tomorrow, but the sequence of events has already been set in motion. Hardware parity has been achieved. The software gap is closing rapidly. The TCO advantages are glaring. For enterprise IT buyers and cloud architects, the message from MLPerf 6.1 is clear: the era of the Nvidia monopoly is ending, and the era of the open, AMD-powered AI data center has arrived. Plan your budgets accordingly.

As President and Principal Analyst of the Enderle Group, Rob provides regional and global companies with guidance in how to create credible dialogue with the market, target customer needs, create new business opportunities, anticipate technology changes, select vendors and products, and practice zero dollar marketing. For over 20 years Rob has worked for and with companies like Microsoft, HP, IBM, Dell, Toshiba, Gateway, Sony, USAA, Texas Instruments, AMD, Intel, Credit Suisse First Boston, ROLM, and Siemens.